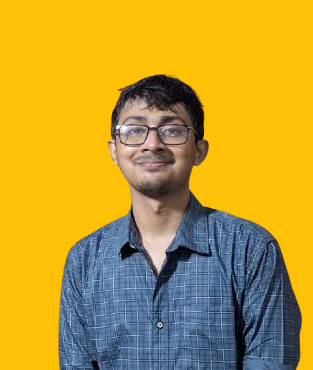
I'm Ovi, a software engineer at IQVIA and a BUET graduate with research experience in NLP. My work connects enterprise LLM assistants with hands-on projects in retrieval, agent workflows, and model fine-tuning.
Contributed to a collaborative PRISMA 2020 systematic review of fairness and bias in histopathology AI, synthesizing 78 studies published between 2017 and 2026.
Work included an eight-category bias taxonomy, analysis of fairness evaluation and debiasing practices, and a proposed reporting checklist and benchmark specification.
Explored code-review comment classification with CodeBERT embeddings and AST/change-based metrics at the Bangladesh University of Engineering and Technology.
Tool-augmented reasoning, retrieval, agent behavior, and evaluation.
02
Language & software
Language and code representations, program analysis, and developer assistance.
03
Trustworthy AI
Reliability, fairness, bias evaluation, and external validation.
Selected work
Selected engineering work.
From model comparison and fine-tuning to retrieval pipelines and stateful agents. Explore the problem, implementation, and outcome behind each project.
Applied AI projects
Fine-tuning, agent workflows, and retrieval systems
6
01 / Model engineering
Amazon Product Price Prediction — LLM & ML Engineering
2026
LLM Engineering Capstone · 2026
Predicting a product's price from its description is a practical way to compare language representations, model families, and adaptation strategies. I built a pipeline from Amazon product-data curation through classical baselines, neural models, API-based LLMs, and QLoRA fine-tuning.
LLM-assisted text preparation, reusable inference and evaluation, and 4-bit QLoRA adaptation with PEFT. Experiments span a 20K-sample lite configuration and a full 800K dataset.
Finding & scope
QLoRA recorded the lowest reported MAE in this project's comparison. Fine-tuning was not uniformly better: GPT-4.1-nano fine-tuning recorded $75.91. These results describe this task and experimental setup.
Explore the experiment pipeline
Curated and preprocessed noisy Amazon product metadata from the McAuley Amazon Reviews 2023 dataset into model-ready text representations.
Used the Groq API to transform raw listings into compact structured descriptions; prepared a 20K-sample curated dataset (up to 800K in later experiments).
Established NLP/ML baselines with Bag-of-Words / vectorization and Linear Regression, Random Forest, and XGBoost ($68.23 MAE).
Built a custom PyTorch network over vectorized features ($46.49 MAE) and benchmarked zero-shot frontier LLMs on the same task.
Fine-tuned GPT-4.1-nano via the OpenAI API and compared against zero-shot baselines, including cases where fine-tuning did not improve performance for the available training setup.
Fine-tuned Llama 3.2 3B with QLoRA/PEFT and 4-bit quantization; achieved the lowest MAE ($39.85) among evaluated classical ML, neural, and LLM-based approaches.
Developed a reusable evaluation framework with parallel inference, MAE benchmarking, Plotly visualization, and error analysis across 15+ model variants.
Agentic Chatbot — LangGraph Multi-Use AI Assistant
2025
Designed and implemented a stateful agentic workflow using LangGraph, with specialized nodes for conversational reasoning, web search, and news aggregation. Implemented state management, conditional routing, caching, retries, and tool integration to support reliable multi-step agent execution. Built with Streamlit for a unified interface and Tavily API for real-time search.
Built a retrieval-augmented news intelligence system using OpenAI, LangChain, and FAISS. Users load article URLs or text files into a semantic index and ask context-aware questions with cited responses. Designed an end-to-end RAG pipeline with Streamlit UI for efficient research workflows.
From source articles to grounded answers
01 / CollectURLs or textFetch & prepare sources
02 / IndexEmbeddings + FAISSPersist a semantic index
Source ingestion, semantic retrieval, a reusable local FAISS index, and a Streamlit question-answering interface.
Outcome & scope
A documented application and video demo for exploring indexed articles. Citations support source inspection; the project does not establish answer faithfulness through a formal benchmark.
Developed a multi-agent system using Model Context Protocol (MCP) and Google Gemini, orchestrated with LangGraph. Built and connected custom MCP servers—Weather (Go) and Calculator (Python)—through Gemini's tool-use framework to answer weather and calculation queries via tool-augmented agent reasoning.
Designed a multi-stage agentic pipeline for automated blog generation. Specialized agents handle topic generation, web research, outline planning, and article drafting, coordinated by a central workflow controller for structured reasoning and modular content generation.
Developed an AI-assisted personal finance application that tracks expenses, analyzes spending patterns, and generates intelligent insights. Applies AI-driven analysis to provide personalized budgeting recommendations and expense optimization.
Structured implementation work — weekly labs across LLM engineering and agentic systems
2
LLM Engineering — Core AI Engineer Track
2026
An implementation-focused eight-week exploration of modern LLM engineering — from LLM applications and multi-model systems through Hugging Face/Transformers, RAG, vector databases, fine-tuning (LoRA/QLoRA), deployment, and agentic AI. Repository organized by week for inspectable, hands-on progress.
Full-stack MERN application where users can discover local businesses,
create business profiles, leave reviews, provide star ratings, and upload photos.
Work on evaluation correctness, training reliability, retrieval systems, and parameter-efficient fine-tuning.
· 6 open pull requests · 1 open issue
Agent memory2 open PRs
Graphiti
Temporal retrieval and graph reliability
A 21-case Neo4j benchmark measured when historical facts were returned, missed, or mixed with facts from the wrong period. A separate patch lets Neo4j save entities with optional embeddings.
21 retrieval cases · live Neo4j
Technical overview
Submitted documentation and a regression test for point-in-time retrieval, including queries at the boundary between two facts.
Independently reproduced two retrieval failures and validated existing patches for combined date filters and full-text candidate limits. The second patch recovered the valid fact at rank one behind 30 superseded candidates.
Partially deleted documents could retain a healthy-looking status. The submitted change exposes deletion-in-progress state and keeps interrupted work visible for retry.
Deletion lifecycle tests · status & UI changes
Technical overview
Problem: interrupted cleanup can leave document status inconsistent with stored data.
Change: track DELETING state, isolate it from ingestion, preserve it during scans, and expose it in the interface.
Evidence: focused deletion lifecycle and frontend tests described in the PR.
A value valid as a Python float can become infinity in float32. The submitted change rejects non-finite rewards and out-of-range training values before conversion.
24 CPU regression cases · training-path checks
Technical overview
Cause: a finite value such as 1e40 exceeds float32's finite range.
Change: validate rewards and fallbacks, with errors identifying the rollout. Preserve large finite validation metrics.
Evidence: boundary cases and a local event-API-to-training-tensor reproduction.
The evaluator could extract A from “Answer choice: D.” The submitted fix prioritizes explicit answer formats and narrows the fallback to a unique standalone label.
7 CPU tests passed · CLI regression coverage
Technical overview
Cause: an unconditional regex selected the first capital A/B/C/D anywhere in the response.
Change: recognize bare labels, retain structured patterns, and use a unique standalone-letter fallback.
Evidence: failing baseline tests, passing unit and CLI tests, and open-ended QA controls.
Weighted merging can inherit the first adapter's exclusion filters and drop layers from another source. The submitted fix preserves the layers each source actually adapts.
Tests cover both source orders, list and regex exclusions, and saving and reloading the combined adapter. Existing LoRA and IA³ checkpoints produced identical outputs before and after the change in three CPU dtypes.
I translate domain requirements, client feedback, and data semantics into prompts, agent instructions, and behavioral constraints.
Design and refine system prompts; investigate failure cases and validate responses against business rules and domain documentation.
Work on prompt configuration, behavior analysis, and evaluation within LangChain/LangGraph-based systems, with LangSmith for observability.
Previously developed cloud storage, document management, authentication, and security features using .NET Core, Angular, PostgreSQL, and AWS S3.
Jun 2023 — Jan 2024Software Engineer I
Enosis Solutions
Full-stack engineering · E-learning
Contributed to an education platform using ASP.NET Core, Angular, and SQL Server, building application modules, improving performance, and resolving reliability issues.
Explored NLP and code representations for code-review feedback classification, supervised by Dr Anindya Iqbal.
About
Ovi Poddar
A software engineer with a research background in NLP and software engineering.
I work at the intersection of LLM behavior, domain requirements, and evaluation. Alongside my work at IQVIA, I build projects in RAG, parameter-efficient fine-tuning, and agentic systems.
My research interests span applied LLMs, agentic AI, NLP, and trustworthy AI. I am interested in PhD opportunities that connect these areas with practical, reliable systems.
Awarded the Dean's List distinction at BUET for maintaining a
CGPA of 3.75 or higher across all semesters of Level-2.
Competitive Programming
Solved 2500+ problems on Codeforces, LeetCode, and other platforms,
demonstrating expertise in algorithms, data structures, and optimized problem-solving.
Recognized for delivering higher-than-expected contributions, taking ownership
in the absence of a tech lead, and ensuring stability and timely feature delivery.
Talent Pool Scholarship
Awarded the Talent Pool Scholarship in both Secondary and Higher Secondary
Examinations in Bangladesh for outstanding academic performance.
Contact
Let's talk research & engineering.
For research collaborations, PhD opportunities, and conversations about applied AI.